A Technical SEO Checklist That Prioritizes What Actually Moves Rankings
09/30/2026
Web Dev
A technical SEO checklist only pays off when you run it in order, fixing crawlability, rendering, and speed before you touch schema, internal links, or monitoring.
Run this order every time: crawlability, then rendering, then speed, then mobile, then schema, then internal links, then status codes, then monitoring. Skip a step and you'll spend a week optimizing Core Web Vitals on a page Google can't even index.


Pre-Audit Checks, Crawlability, and Whether Bots See Your Content
Here's the priority breakdown we use on every engagement. High priority covers anything blocking discovery or indexing, fix it within 48 hours. Medium priority covers rendering, speed, and schema gaps, fix within one sprint. Low priority covers polish items like internal link anchor text and pagination cleanup, schedule for the next quarterly pass.
Before touching a single meta tag, run these:
- Google Search Console → Coverage report, check for spikes in "Excluded" or "Error"
- curl -s [URL] → compare raw HTML against what renders in a browser
- Lighthouse or PageSpeed Insights → grab lab scores for LCP, INP, CLS
- Chrome UX Report (CrUX) → pull real-user field data for the same metrics
- Server log grep for 403, 500, and bot user-agent patterns from the last 30 days
Everything below explains how to run them properly and what the results actually mean.
Key Takeaways
A technical SEO checklist only works when crawlability, rendering, and speed are fixed before schema, links, or monitoring, since each later layer depends on the one before it.
| Point | Details |
|---|---|
| Fix crawlability first | Resolve Google Search Console coverage errors before optimizing anything downstream. |
| Verify raw HTML | Use curl to confirm AI crawlers see the same content browsers do, not just a JavaScript shell. |
| Prioritize LCP | With roughly 49.1% of sites failing Core Web Vitals, LCP fixes usually deliver the fastest gains. |
| Write for extraction | Place key facts in the first 30% of the page and make sentences self-contained for AI citation. |
| Delegate what you can't staff | The Branded Agency runs the audit, prioritizes fixes by impact, and provides the engineering support to implement them. |
Technical SEO Checklist Step One: Crawlability and Indexing
If Google can't crawl it, nothing else on this list matters. Start in Google Search Console's Coverage report and sort by status. "Indexed" is your baseline. "Excluded" needs a reason, duplicate content, crawled but not indexed, or a noindex tag you forgot about. "Error" needs same-day attention.
Pull up robots.txt at the root domain and read it line by line, not just skim it. A single misplaced Disallow: / under the wrong user-agent block has taken down entire sections of otherwise healthy sites. Test specific URLs against the file using Search Console's URL Inspection tool, and check the X-Robots-Tag HTTP header too, since it can override what's in your HTML meta tags without anyone noticing.
Your XML sitemap needs three things: accurate lastmod dates, only canonical URLs (never redirects or noindexed pages), and successful submission status in GSC. A sitemap padded with 404s or redirected URLs tells Google your data hygiene is poor across the board.
Watch for the canonical plus noindex conflict specifically. Some CMS platforms apply both tags to the same page automatically, and it's a coin flip which one search engines honor.
| Test | Tool or command | Interpretation | Next step |
|---|---|---|---|
| Coverage status | Google Search Console | Excluded pages need a documented reason | Fix or reclassify each excluded URL |
| Robots.txt syntax | curl + GSC robots tester | Blocked resources (CSS and JS) can break rendering | Remove overly broad Disallow rules |
| Sitemap accuracy | GSC Sitemaps report | 4xx URLs in sitemap signal poor hygiene | Strip dead URLs, resubmit |
| Server response codes | Log file grep for 403 errors | Repeated bot 403s suggest a WAF blocking crawlers | Whitelist verified crawler IPs |
Pro Tip: Run grep "Disallow" robots.txt alongside a spot check of your CSS and JS directories. Blocking a shared asset folder by accident is one of the most common self-inflicted crawlability wounds we find in audits.
Server logs tell you what GSC can't: exactly which bot hit which URL and got which response code. When GSC says a page is "crawled, not indexed" but your logs show Googlebot hasn't visited it in three weeks, trust the logs. They're closer to ground truth.
Does Your Site Serve The Same Content To Bots As Browsers?
Most modern sites lean on JavaScript for critical content, and that's a problem because many major AI crawlers don't render JavaScript at all. They fetch raw HTML and leave. If your product descriptions, pricing, or main article body only appear after a client-side script fires, those crawlers see a blank shell.
Test it yourself with curl -s [URL] piped into a text file, then compare that raw output against what you see in a browser's View Source (not Inspect Element, which shows the rendered DOM after JavaScript runs). If your hero content, headings, and body copy are missing from the curl output but present in the browser, you have a rendering gap.
The fix is server-side rendering, static site generation, or pre-rendering, depending on your stack:
- Next.js and Nuxt support SSR and SSG out of the box for React and Vue projects
- Angular Universal handles server-side rendering for Angular applications
- E-commerce platforms should lean toward SSR, SSG, or incremental static regeneration for product pages specifically, since those pages carry the highest commercial intent
Not every page needs this treatment. Prioritize templates by traffic and conversion value: product pages, category pages, and cornerstone articles go first. Internal tools or logged-in dashboards can stay client-rendered indefinitely.
Pro Tip: Don't audit one URL per template and call it done. Pull five to ten sample URLs from each template type and curl all of them. Rendering gaps often show up on some pages within a template but not others, depending on conditional logic in the code.
Free Brand Health Audit
Make sure your brand is built to sell
Search has changed. Your customers aren't just Googling anymore. They're asking ChatGPT, Perplexity, Gemini and other AI platforms what to buy, who to trust and which brands they should consider.
If your brand isn't showing up clearly in those answers, you're already losing opportunities. Our free Brand Health Audit shows you where your brand stands across traditional search, AI search and brand positioning.

Sample brand audit
Live preview
Traditional search
72
AI search (GEO)
34
Brand positioning
58
Core Web Vitals, Mobile Usability, and Schema Priorities
How Do You Fix Core Web Vitals Problems?
Field data currently shows that only about 49.1% of sites pass Core Web Vitals across a large CrUX sample, and LCP is usually the metric dragging that number down. If your site is in the failing half, you're not alone, but you are leaving both rankings and conversion rate on the table.
Run lab tests with Lighthouse or PageSpeed Insights for a controlled snapshot, but don't stop there. Lab data reflects a single simulated session; field data from CrUX reflects what real visitors on real devices and real connections actually experienced. A page can score 95 in Lighthouse and still fail in the field if your actual mobile users are on throttled connections your lab test didn't simulate.
Here's how the three metrics typically break down in practice:
| Metric | Common cause | Concrete fix |
|---|---|---|
| LCP (Largest Contentful Paint) | Oversized hero image, slow server response | Serve AVIF or WebP, add fetchpriority="high" to the hero image |
| INP (Interaction to Next Paint) | Heavy JavaScript blocking the main thread | Defer non-critical scripts, break up long tasks |
| CLS (Cumulative Layout Shift) | Images and ads without reserved dimensions | Set explicit width and height attributes on all media |
Third-party scripts, chat widgets, ad tags, analytics pixels, are frequent hidden culprits. WebPageTest lets you script a test that blocks individual scripts one at a time and re-measures load performance, which isolates exactly how much each one costs you in milliseconds. For image-heavy WordPress sites, a plugin like WP Smush can compress assets automatically, though you should spot-check output quality before rolling it out sitewide.
When you interpret results, watch for lab anomalies (a single slow test run skewing your average) and always segment mobile from desktop. Mobile-first indexing means Google evaluates your mobile experience regardless of how fast your desktop site loads.
Pro Tip: Use WebPageTest's scripting feature to load the page normally, then load it again with your top three third-party scripts blocked via blockDomains. The delta in LCP and INP between the two runs tells you exactly which vendor is costing you the most.
Is Your Mobile Experience Actually Passing?
Google's Mobile-Friendly Test and Lighthouse's mobile emulation mode are your two starting points, and they catch different things. The Mobile-Friendly Test flags viewport configuration and tap target spacing. Lighthouse mobile emulation gives you a full performance and accessibility score under simulated mobile conditions.
The recurring offenders across most audits:
- Missing or misconfigured viewport meta tag, causing desktop layouts to render at mobile widths
- Tap targets spaced closer than 48 pixels, triggering accidental taps
- Font sizes under 12px that force users to pinch and zoom
- Images or ads that load late and shift content, spiking your mobile CLS score
Lazy-loading and infinite scroll deserve extra scrutiny on mobile specifically. If your infinite-scroll implementation loads content only on scroll events triggered by JavaScript, crawlers that don't execute scripts, and some that do but don't scroll, will never see content past the first viewport. Test this by disabling JavaScript in your browser's dev tools and reloading the page. Whatever's missing is invisible to a large share of both AI and traditional crawlers.
Prioritize viewport and tap target fixes first. They take a developer an afternoon and immediately affect every mobile visitor and every mobile crawl.
Pro Tip: Test infinite scroll pages with curl -s the same way you'd test JavaScript rendering. If your paginated content only exists behind a "load more" button that fires via JavaScript, add a paginated fallback URL structure so crawlers get a static entry point into every page of content.
Which Schema Types Should You Implement First?
Not all structured data carries equal weight. Research shows pages cited by AI platforms disproportionately implement Organization, Article, and BreadcrumbList schema, which makes those three your starting lineup regardless of industry. Add Product schema for e-commerce, FAQ schema for support content, and HowTo schema for instructional pages.
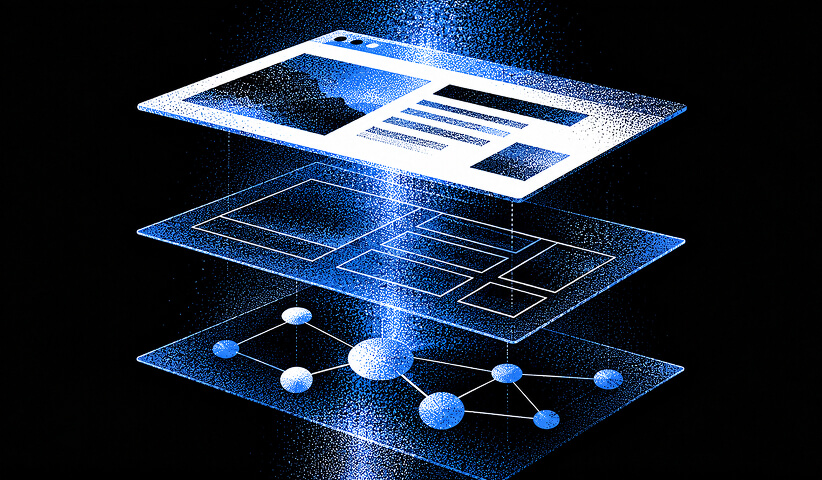
Implement everything as JSON-LD in the page <head> rather than microdata or RDFa scattered through the HTML body. It's easier to maintain, easier to template, and Google's own documentation favors it. Validate every implementation with the Rich Results Test and a general Schema.org validator before pushing to production, and re-check after any template change, since a single broken comma in a JSON-LD block invalidates the entire schema silently.
Structured data doesn't work in isolation. Heading hierarchy and semantic HTML have become essential signals for both accessibility and AI extractability, and poorly structured HTML turns into what one industry analysis bluntly calls "soup" that machines struggle to parse. Use <nav>, <main>, and <article> landmark elements properly, keep one <h1> per page, and never skip heading levels just to control visual size in CSS.
- Confirm heading order flows h1 → h2 → h3 without skipping levels
- Wrap primary content in <article> and navigation in <nav>
- Validate every JSON-LD block after deployment, not just at launch
- Add sameAs properties linking to verified social and knowledge-graph profiles
Pro Tip: Use the sameAs property in your Organization schema to link to your verified LinkedIn, Crunchbase, and Wikipedia profiles where they exist. This strengthens entity recognition and gives AI systems corroborating sources beyond your own site.
Optimizing Core Web Vitals on pages Google can't even index? Keep reading!
If you need a technical SEO audit and the engineering support to actually fix what it finds, contact us for a free custom quote.
Site Architecture, Redirects, HTTPS, and Ongoing Monitoring
Are Your Most Important Pages Buried Too Deep?
Orphan pages, content with zero internal links pointing to it, are invisible to crawlers no matter how good the writing is. Run a full crawl with Screaming Frog, export the internal link count per URL, and filter for anything at zero. Cross-reference against your sitemap and analytics; if a page gets organic traffic but shows up as orphaned in your crawl, you likely have an inconsistent internal linking pattern that needs fixing before it's fully deindexed.
Path depth matters almost as much as link count. Target a maximum crawl depth of three to four clicks from the homepage for any page you want ranked. Screaming Frog's crawl depth report will show you exactly which cornerstone pages are buried six or seven clicks deep in your architecture, usually a symptom of category pages with no clear hub-and-spoke structure.
On URLs, keep slugs descriptive but short, /services/website-audit beats /services/technical-website-seo-audit-and-remediation-services. Handle URL parameters (sorting, filtering, session IDs) with canonical tags pointing to the clean version, and decide deliberately whether faceted navigation combinations should be indexed, canonicalized, or noindexed based on whether they target real search demand.
- Run a Screaming Frog crawl and filter for pages with zero inbound internal links
- Set a hub page for every core topic and link supporting content back to it
- Canonicalize parameterized URLs to their clean equivalent
- Noindex faceted combinations that don't match real search queries
Pro Tip: Build a simple internal-link priority list ranking your top 20 revenue or traffic pages, then audit whether your highest-authority pages (homepage, top blog posts) actually link to them. Link equity flows where you point it, not where you assume it should go.
How Do You Find And Fix Redirect Chains?
Redirect chains, where URL A redirects to B, which redirects to C, waste crawl budget and dilute link equity at every hop. Run a full Screaming Frog crawl with "Always Follow Redirects" enabled in the spider settings, then check the Redirect Chains report. Anything longer than two hops needs collapsing to a single direct redirect.
Use 301s for anything permanent. Reserve 302s for genuinely temporary situations, like an A/B test variant, and audit your site periodically for 302s that have quietly become permanent fixtures, a common leftover from rushed migrations.
Cross-check crawl results against server logs to catch bot-specific problems Screaming Frog might miss, particularly 403 responses served only to specific user agents. A WAF rule blocking an AI crawler by IP range won't show up in a standard browser-based crawl.
- Export the Redirect Chains report and collapse anything with more than one hop
- Confirm every permanent move uses a 301, not a 302
- Never pair a canonical tag pointing to URL A with a noindex tag on URL A
- Cross-reference 4xx crawl errors against your server logs for bot-specific patterns
Pro Tip: Filter your server logs with grep " 403 " access.log | grep -i bot to isolate exactly which crawlers are getting blocked and on which URLs. Compare that list against your Screaming Frog crawl to confirm whether the block is intentional or a configuration accident.
Is HTTPS Actually Configured Correctly?
Check your TLS certificate's validity and chain first, an expiring certificate or a broken intermediate chain will trigger browser warnings that tank both trust and conversion rate. Confirm HSTS is properly configured and that every HTTP request redirects cleanly to HTTPS with a single 301, not a chain.
Mixed content, HTTPS pages that still load images, scripts, or stylesheets over plain HTTP, breaks the padlock icon and can silently block those resources in modern browsers. Scan your source code for hardcoded http:// references and update them to protocol-relative or explicit HTTPS URLs.
Security issues affect more than user trust. A misconfigured certificate can cause crawlers to abandon a fetch entirely, and malware attacks remain a real risk factor worth building into your ongoing monitoring rather than treating as a one-time check.
- Verify certificate validity and full chain resolution
- Confirm HSTS headers are present and correctly scoped
- Scan for and eliminate mixed HTTP content on HTTPS pages
- Test that all HTTP requests 301 redirect to HTTPS in a single hop
What Should You Monitor After The Initial Audit?
A technical audit isn't a one-time event. Keep four systems live at all times: Google Search Console for coverage and manual action alerts, server logs for bot behavior, Cloudflare or your CDN's analytics dashboard for traffic and threat patterns, and Lighthouse CI wired into your deployment pipeline to catch performance regressions before they ship.
Cloudflare and similar CDN services now provide bot analytics that identify specific AI crawler types and volumes, which makes log-based analysis your most reliable method for confirming what's actually happening, GSC and dashboard summaries lag behind real-time bot activity.
Filter your logs for GPTBot, ClaudeBot, and ChatGPT-User alongside traditional search bots, and confirm each one is getting consistent 200 responses on the pages you want them to see. A sudden drop in bot visits or a new pattern of 403s usually means a WAF rule or CDN setting changed without anyone flagging it to the SEO team.
- Set a recurring monthly log review specifically for AI crawler user agents
- Watch for sudden volume drops in any single bot's crawl pattern
- Wire Lighthouse CI into your CI/CD pipeline to catch speed regressions pre-launch
- Cross-check GSC coverage weekly against your own crawl exports
Pro Tip: After shipping any fix, rerun the same log query from before the change and confirm the error rate actually dropped. A fix that "should work" and a fix that's verified in production logs are two different things, don't close the ticket until you've confirmed the second one.
AI Crawler Readiness, the Full Checklist, and How We Run Audits
How Do You Prepare For AI Crawlers Specifically?
AI crawlers aren't one monolithic category. They split into training crawlers, search and retrieval crawlers, and user-triggered agents, and each deserves its own deliberate robots.txt decision rather than a blanket allow or block. Blocking a training crawler might align with your content licensing preferences; blocking a retrieval crawler that powers a live AI answer engine could cut off a growing referral channel entirely.
Audit your robots.txt and any WAF or CDN rules against the current list of major AI user agents, and check your logs for 403 patterns specifically tied to those agents. It's common to find a WAF blocking AI bots by default with nobody having made that call intentionally.
Beyond crawler access, look at your accessibility tree. Inspect it using your browser's dev tools (Accessibility panel in Chrome) and confirm the structure assistive technology sees matches your visual heading hierarchy. AI agents that parse page structure often rely on similar signals, a page that's visually organized but semantically flat, all <div>s with no real headings, gives both screen readers and AI systems very little to work with.
Content extractability is the newest layer here, and the numbers back its importance: roughly 44.2% of AI citations pull from the first 30% of a page. Put your strongest claims, figures, and definitions early. Then write those key sentences so they stand alone. AI retrieval systems often extract single passages, and a sentence that depends on "this" or "it" referring back to a previous paragraph reads as gibberish when pulled out of context.
- Categorize AI crawlers by type and set deliberate robots.txt rules for each
- Inspect the accessibility tree and compare it against your visual heading structure
- Move your most citable facts and figures into the first 30% of the page
- Rewrite pronoun-dependent sentences so each stands alone if quoted in isolation
Pro Tip: Take any paragraph that opens with "This means..." or "It shows..." and rewrite it to name the subject explicitly.
The Full Checklist Template You Can Copy
Here's every check from this guide consolidated into one reference table, ordered by the sequence we recommend running them in.
| Check | Tool or command | How to interpret | Impact | Time to fix |
|---|---|---|---|---|
| Coverage & indexing | Google Search Console | Excluded or Error pages need documented cause | High | 1 to 3 days |
| Raw HTML vs. rendered content | curl -s [URL] + View Source | Missing content in curl output = rendering gap | High | 1 to 2 weeks (engineering) |
| Core Web Vitals | Lighthouse, PageSpeed Insights, CrUX | Field data over lab data for real user impact | High | 3 days |
| Mobile usability | Google Mobile-Friendly Test, Lighthouse mobile | Viewport and tap target errors are quick wins | Medium | 1 to 2 days |
| Structured data | Rich Results Test, Schema validator | Invalid JSON-LD invalidates entire schema block | Medium | 1 day |
| Internal linking & orphans | Screaming Frog crawl export | Zero-inbound-link pages need hub placement | Medium | 3 days |
| Redirects & status codes | Screaming Frog redirect chain report | Chains over 2 hops need collapsing | Medium | 1 to 2 days |
| HTTPS & mixed content | Browser dev tools, SSL checker | Any HTTP resource on HTTPS page needs updating | Low | 1 day |
| AI crawler access | robots.txt review, log grep for AI bots | Unintentional 403s to AI agents cut visibility | Medium | 1 day |
For your first sprint, tackle coverage errors, rendering gaps, and Core Web Vitals, those three alone typically resolve the majority of visibility problems on a mid-sized site. Schema, internal linking, and redirect cleanup can roll into sprint two without meaningfully delaying results.
Smaller sites can run this entire checklist manually in a day or two. Enterprise sites with multiple templates and content types should break it into a per-template audit, since a fix validated on one page type won't automatically apply across a different one.
Pro Tip: After remediation, track three KPIs weekly for the first month: GSC "Indexed" page count, average LCP from CrUX, and bot error rate from your server logs. If all three trend the right direction, your fixes are working. Set a recurring quarterly audit after that to catch drift before it compounds.
How We Run A Technical SEO Audit
Our process follows six stages: prepare, crawl, review logs, prioritize, fix, verify. Preparation means pulling GSC and CrUX data before touching anything, so we have a real baseline instead of guessing. The crawl and log review happen in parallel, since Screaming Frog shows structural problems while logs show what's actually happening with real crawler traffic, and the two data sets frequently disagree in revealing ways.
We lean on field data from CrUX to validate what lab tools like Lighthouse suggest, because a meaningful share of AI visibility improvements turn out to be repayment of old technical debt rather than net-new optimization. Fixing a rendering gap that's existed for two years often produces a bigger jump than any new tactic would.
Pro Tip: When you brief stakeholders, separate "quick wins" from "technical debt." Quick wins buy credibility for the bigger, slower architectural fixes that actually move the needle.
Delegate The Audit And Remediation Work
Running this checklist properly, crawling, log analysis, rendering checks, schema validation, redirect cleanup, takes real hours away from campaign work, and most in-house teams don't have a developer on standby to fix what the audit finds. The Branded Agency runs the full audit, hands you a prioritized remediation plan ranked by impact and time-to-fix, and brings the engineering support to actually implement it, not just diagnose it.
A paid audit engagement typically scopes to a full crawl, log review, Core Web Vitals analysis, and a structured data and rendering assessment, delivered as a prioritized action plan your team or ours can execute against. We coordinate directly with your developers or handle the website development and remediation work ourselves, then verify the fixes in the field data afterward instead of just declaring victory at deployment. If your site runs on Webflow, our Webflow-specific development team handles the template-level rendering fixes that generic dev shops often miss.
Get in touch to scope a technical audit for your site, and we'll tell you upfront what we expect to find and what it'll take to fix it.
Sources
Recommended
Quincy Samycia
As entrepreneurs, they’ve built and scaled their own ventures from zero to millions. They’ve been in the trenches, navigating the chaos of high-growth phases, making the hard calls, and learning firsthand what actually moves the needle. That’s what makes us different—we don’t just “consult,” we know what it takes because we’ve done it ourselves.
Want to learn more about brand platform?
If you need help with your companies brand strategy and identity, contact us for a free custom quote.
We do great work. And get great results.
+2.3xIncrease in revenue YoY
+126%Increase in repurchase rate YoY

+93%Revenue growth in first 90 days
+144% Increase in attributed revenue


+91%Increase in conversion rate
+46%Increase in AOV
+200%Increase in conversion rate
+688%Increase in attributed revenue